MySQL to Kafka
NineData Data Replication supports full and incremental replication from MySQL-compatible data sources to Kafka.
Overview
Use this workflow to deliver MySQL changes to Kafka as Canal JSON, Debezium JSON, or Avro messages for downstream stream processing, analytics, monitoring, and data distribution workloads. See Appendix 1 for Canal JSON fields, Appendix 2 for the Debezium JSON structure, and Appendix 3 for the Avro schema structure and encoding. Avro schemas are managed through Confluent Schema Registry.
Before you begin
Add the source and target data sources to NineData. For details, see Add Data Source.
The supported MySQL source versions range from 5.1 to 9.0.
The target data source must be Kafka 0.10 or later.
The source data source must have Binlog enabled, with the following parameters:
binlog_format=ROWbinlog_row_image=FULLtipIf the source data source is a standby database, enable
log_slave_updatesto capture the complete Binlog.
Restrictions
Data replication applies only to user databases. System databases are not replicated. For MySQL data sources, system databases include
information_schema,mysql,performance_schema, andsys.Before data synchronization, evaluate source and target performance, and run synchronization during off-peak hours when possible. Full data initialization consumes read and write resources on both sides and increases database load.
Make sure each replicated table has a primary key or unique constraint, and that column names are unique. Otherwise, duplicate rows may be synchronized.
Procedure
Sign in to the NineData Console.
In the navigation menu, click Replication > Data Replication.
On the Replication page, click Create Replication.
On the Source & Target tab, configure the source, target, and Kafka delivery settings, and then click Next.
Parameter Description Name Enter a meaningful data replication task name for later search and management. Up to 64 characters are supported. Source Select the MySQL data source that contains the data to replicate. Target Select the Kafka data source that receives the replicated data. Kafka Topic Select the Kafka topic that receives the replicated MySQL data. Delivery Partition Select how NineData delivers messages to Kafka partitions. - Deliver All to Partition 0: Deliver all messages to partition 0.
- Deliver to different partition by the Hash value of [databaseName + tableName]: Hash by source database name and table name.
- Deliver to different Partitions based on the Hash value of [table name + primary key value]: Hash by table name and primary key value, and deliver messages to different partitions.
Delivery data format Select Canal JSON, Debezium JSON, or Avro. Avro uses Confluent Schema Registry to manage message schemas. See Appendix 2 for the Debezium JSON message structure and Appendix 3 for Avro schemas. Confluent Schema Registry service address Enter the Confluent Schema Registry endpoint for Avro, for example, <schema-registry-host>:<port>.Username or API Key For Avro, enter the Schema Registry username or API key when authentication is required. Password or Secret For Avro, enter the Schema Registry password or secret when authentication is required. Type Select Full or Incremental for the replication task. - Full: Replicate all selected source objects and data. This is full data replication.
- Incremental: After full replication completes, replicate incremental changes based on the source logs. Click the
 icon to clear operation types that you do not want to replicate during incremental synchronization. Cleared operations are ignored.
Incremental Started Required only when Type is Incremental. - From Started: Start incremental replication from the time when the replication task starts.
- Customized Time: Select a custom time point for incremental replication. Select the time zone that matches your business location. If the time point is earlier than the task start time and DDL operations exist in that period, the task fails.
Target Table Preparation Target Table Exists Data - Pre-Check Error and Stop Task: Stop the task if the precheck detects existing data in the target topic.
- Ignore existing target data and append to it.: If the precheck detects existing data in the target topic, ignore that data and append new data.
- Clear target existing data before write: If the precheck detects existing data in the target topic, delete the existing data before writing new data.
On the Objects tab, configure the following parameters, then click Next.
Parameter Description Replication Objects Select the objects to replicate. Select Full Instance to replicate all objects in the source database, or select Customized Object, choose objects in the Source Object list, and click > to move them to the Target Object list. Blacklist (optional) Click Add to add a blacklist rule. Select the databases or objects to exclude from replication. Blacklist rules are used to exclude specific databases or objects when Customized Object or Full Instance replication is selected. - Left drop-down list: Select the database to add to the blacklist.
- Right drop-down list: Select one or more objects in the selected database. Leave this field empty to add the entire database to the blacklist.
On the Mapping tab, configure the columns to replicate to Kafka. By default, NineData replicates all columns in the selected tables.
On the Pre-check tab, wait for NineData to complete the precheck. After the precheck passes, click Launch.
tip- If the precheck fails, click Details in the Actions column for the failed item to view the cause. After fixing the issue, click Check Again to run the precheck again.
- For items whose Result is Warning, fix the issue or ignore the warning when appropriate.
On the Launch page, the Launch Successfully message appears, and the replication task starts running. Use these actions to review the task:
- Click View Details to view the execution status of each replication phase.
- Click Back to list to return to the Replication task list.
Kafka delivery settings
When the task uses one Kafka topic for all selected replication objects, the Delivery Partition setting includes the strategy that hashes by table name and primary key value. When each table uses its own topic, the page does not show the partition setting.
When configuring the Kafka target during task creation, choose how topics are assigned: use one topic for all objects selected in the task, or generate a separate topic for each table. For the shared-topic option, select the target topic with Kafka Topic. The per-table option does not show a shared-topic selector or the partition setting.
Each per-table topic name joins tableTopicPrefix, the source database name, and the source table name with periods. For example, when the prefix is ninedata, the pattern is ninedata.<databaseName>.<tableName>.
With primary-key hashing, INSERT, UPDATE, and DELETE messages for the same primary key retain their order, while rows with different primary keys can be distributed across partitions for parallel consumption. Tables without a primary key fall back to hashing by database and table name. This strategy calculates the partition for each message, so a multi-row batch is split into single-row messages. Hash strategies preserve order only at the table or primary-key level; they do not guarantee global ordering across tables or primary keys. To preserve global ordering, select Deliver All to Partition 0.
To deliver Debezium JSON messages, select Debezium JSON in Delivery data format. See Appendix 2 for the message structure. See Appendix 3 for the Avro schema structure and encoding.
View replication results
Sign in to the NineData Console.
In the navigation menu, click Replication > Data Replication.
On the Replication page, click the ID of the target replication task to open the Details page. The task detail page contains the following areas.
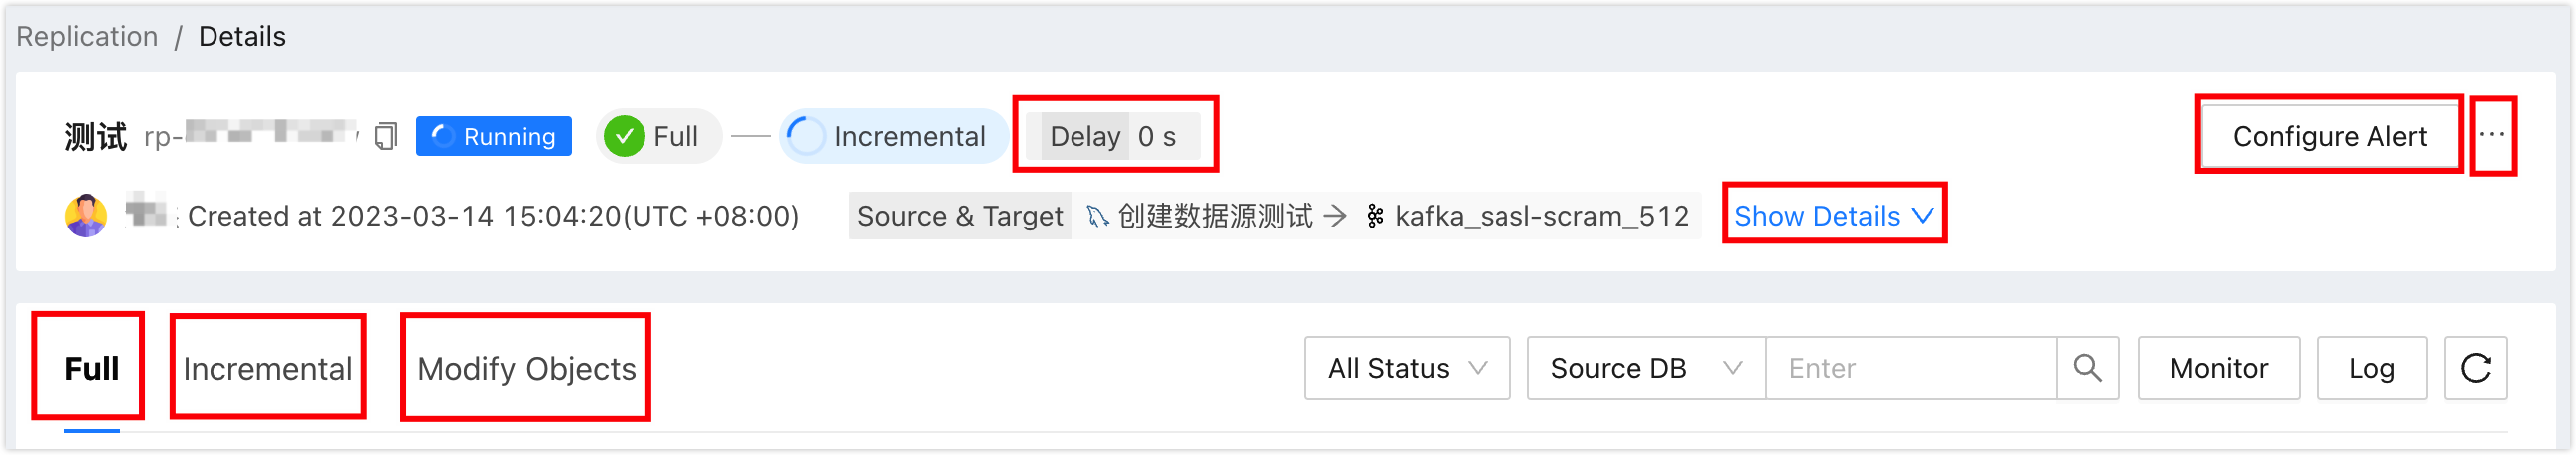
No. Area Description 1 Synchronization Delay Shows the synchronization delay between the MySQL source and Kafka target. 0seconds means the Kafka target has caught up with the MySQL source.2 Configure Alerts After alerts are configured, NineData notifies users when the task fails. For more information, see Introduction to operational monitoring. 3 More - Pause: Pause a task whose status is Running.
- Terminate: Terminate a task that is not complete or is still being monitored, such as a task in incremental synchronization. A terminated task cannot be restarted. Proceed with caution. If the synchronization objects contain triggers, select the trigger replication option that matches your task.
- Delete: Delete the task. Deleted tasks cannot be restored. Proceed with caution.
4 Full Replication (shown when full replication is included) Shows full replication progress and details. - Click Monitor to view full replication metrics. During full replication, click Flow Control Settings on the monitoring page to limit the write rate to the target data source. The unit is MB/s.
- Click Log to view the full replication execution log.
- Click
 to view the latest information.
5 Incremental Replication (shown when incremental replication is included) Shows incremental replication metrics. - Click Flow Control Settings to limit the write rate to the target data source. The unit is rows per second.
- Click Log to view the incremental replication execution log.
- Click to view the latest information.
6 Modify Object Shows the modification history of replicated objects. - Click Modify Objects to configure replication objects .
- Click to view the latest information.
7 Expand Shows task details, including Type, Replication Objects, and Started.
Appendix 1: Canal JSON message format
Data replicated from MySQL to Kafka is stored in JSON format. NineData divides MySQL data into multiple JSON objects, and each JSON object is delivered as a Kafka message.
- During full replication, the number of MySQL rows stored in a single message is determined by the message.max.bytesmessage.max.bytes is the maximum message size allowed in the Kafka cluster. The default value is `1000000` bytes (1 MB). Adjust this value in the Kafka configuration file so that each message can store more MySQL rows. Setting this value too high may reduce Kafka cluster performance because Kafka must allocate memory for each message. parameter.
- During incremental replication, a single message stores one MySQL row.
Each JSON object contains the following fields:
| Field name | Field type | Description | Example |
|---|---|---|---|
| serverId | STRING | Data source information for the message, in the format <connection_address:port>. | "serverId":"47.98.224.21:3307" |
| id | LONG | Record ID of the message. This field is globally incremented and can be used to identify duplicate message consumption. | "Id":156 |
| es | INT | Has different meanings in different task phases:
| "es":1668650385 |
| ts | INT | The time when the message was delivered to Kafka, represented as a Unix timestamp. | "ts":1668651053 |
| isDdl | BOOLEAN | Indicates whether the data is DDL.
| "is_ddl":true |
| type | STRING | Data type.
| "type":"INIT" |
| database | STRING | Database to which the data belongs. | "database":"database_name" |
| table | STRING | Table to which the data belongs. If the object in the DDL statement is not a table, the value is null. | "table":"table_name" |
| mysqlType | JSON | MySQL data types of the fields, represented as a JSON array. | "mysqlType": {"id": "bigint(20)", "shipping_type": "varchar(50)" } |
| sqlType | JSON | Reserved field. No action is required. | "sqlType":null |
| pkNames | ARRAY | Primary key names for the record in the Binlog.
| "pkNames": ["id", "uid"] |
| data | ARRAY[JSON] | Data delivered from MySQL to Kafka, stored as a JSON array.
| "data": [{ "name": "someone", "phone": "(737)1234787", "email": "someone@example.com", "address": "somewhere", "country": "china" }] |
| old | ARRAY[JSON] | Records incremental replication details from MySQL to Kafka.
For other operations, the value is null. | "old": [{ "name": "someone", "phone": "(737)1234787", "email": "someone@example.com", "address": "somewhere", "country": "china" }] |
| sql | STRING | For incremental DDL operations, records the SQL statement for the operation. For other operations, the value is null. | "sql":"create table sbtest1(id int primary key,name varchar(20))" |
Appendix 2: Debezium JSON message format
Each Kafka message is a Debezium JSON Envelope with top-level schema and payload fields. schema describes the structure and field types in payload in the Kafka Connect style. Tables with the same name and structure reuse the same schema. A DML batch is split into single-row messages, so each message describes one row.
| Field | Type | Description |
|---|---|---|
schema | JSON | Message schema describing the structure and field types in payload. |
payload | JSON | Message data, including row images, source metadata, and the operation type. |
The main payload fields are:
| Field | Type | Description |
|---|---|---|
before | JSON | Row image before the change. It is null for snapshot and INSERT messages, contains the old row for UPDATE, and contains the deleted row for DELETE. |
after | JSON | Row image after the change. It contains the snapshot row or the new row for INSERT and UPDATE, and is null for DELETE. |
source | JSON | Event source metadata, including connector, database and table, and Binlog position information. |
op | STRING | Operation type: r for snapshot read, c for INSERT (including REPLACE), u for UPDATE, d for DELETE, and m for DDL. |
ts_ms | LONG | Time when the message is delivered to Kafka, in milliseconds. |
databaseName, schemaName, database, schema, table, ddl | STRING | Included only in DDL messages. ddl contains the original SQL. database, schema, and table are compatibility fields. DDL messages do not include before or after. |
In payload.source, version is the message format version ninedata-json-2, and the MySQL connector uses connector: "mysql". snapshot is a string: "true" for full snapshot records and "false" for incremental events. payload.source.ts_ms is the source event timestamp, while payload.ts_ms is the time when the message is delivered to Kafka. Both timestamps use milliseconds. Full snapshot messages use op: "r".
The following is an excerpt of an UPDATE message's payload; the schema, source metadata, and timestamp fields are omitted:
{
  "before": { "id": 20, "status": "PENDING" },
  "after": { "id": 20, "status": "ACTIVE" },
  "op": "u"
}
Appendix 3: Avro schema definition
Avro messages use Confluent Schema Registry to manage schemas. In one-topic-per-table mode, the value subject is {topicName}-value. The Kafka message value contains, in order: the fixed marker 0x00 (1 byte), the ID of the schema in Schema Registry (the schema ID, 4 bytes stored most-significant byte first), and the message data encoded in Avro Binary format. The consumer reads the schema ID, retrieves the matching schema from Schema Registry, and uses it to decode the remaining message data.
The top-level message schema is a CdcMessage record. It contains change metadata and a row record generated from the source table structure. The top-level fields are:
| Field | Avro type | Description |
|---|---|---|
serverId | null or string | Source server identifier. |
id | null or long | Message record ID. |
timestamp | long, logical type timestamp-millis | Source Binlog event time, in milliseconds. |
sinkTimestamp | long | Time the message is delivered to Kafka, in milliseconds. |
changeSequence | null or string | Change sequence identifier. |
operation | CdcOperation enum | Change operation. See the enum values below. |
externalSchemaId | int | Schema ID in Schema Registry. |
isDdl | boolean | Whether the message is a DDL message. |
database | string | Source database name. |
schema | null or string | Source schema; usually null for MySQL. |
table | null or string | Source table name; null for DDL that does not target a table object. |
pkNames | null or array<string> | Primary key column names; null for DDL messages. |
sqlType | null or map<string, string> | Mapping of column names to their original MySQL types; null for DDL messages. |
data | null or dynamic row record | Row data after the change. See the table below. |
beforeData | null or dynamic row record | Row data before the change. See the table below. |
sql | null or string | Original DDL statement; null for non-DDL messages. |
The operation enum values and their encoding indexes are:
| Enum value | Encoding index | Meaning |
|---|---|---|
INIT | 0 | Full initialization data. |
INSERT | 1 | INSERT Binlog event, including REPLACE. |
UPDATE | 2 | UPDATE Binlog event. |
DELETE | 3 | DELETE Binlog event. |
DDL | 4 | DDL statement. |
The values of data, beforeData, and sql vary by operation as shown below.
| Operation | data | beforeData | sql |
|---|---|---|---|
INIT | Initialized row | null | null |
INSERT (including REPLACE) | Row after insertion | null | null |
UPDATE | Row after update | Row before update | null |
DELETE | null | Row before deletion | null |
DDL | null | null | Original DDL statement |
A row record is generated from the table structure. Its name is the table name converted to a valid Avro name with _DATA appended, and its namespace is com.jzcloud.kafka.avro. Each column field uses a nullable union type, ['null', <column type>]. If a column name is converted to a valid Avro name, the original name is stored in the jzcloud.column.name property. The Avro type depends on the MySQL column type and definition; the sqlType field records the original MySQL type for each column.
The following example shows a generated row record for one VARCHAR column. The actual fields depend on the source table structure; this is not a complete CdcMessage schema. Consumers should retrieve the actual schema from Schema Registry by using the schema ID in the message:
{
  "type": "record",
  "name": "example_DATA",
  "namespace": "com.jzcloud.kafka.avro",
  "fields": [
    {
      "name": "status",
      "type": ["null", "string"]
    }
  ]
}
Before using Avro, configure the Confluent Schema Registry endpoint. If the registry requires authentication, configure a username and password. The complete MySQL column type mapping depends on the source column definition.
Appendix 4: Precheck items
| Check item | What NineData checks |
|---|---|
| Source data source connection check | Checks the source gateway status, instance accessibility, and username and password. |
| Target data source connection check | Checks the target gateway status, instance accessibility, and username and password. |
| Source database permission check | Checks whether the source database account has the required permissions. |
| Source standby log update check | Checks whether log_slave_updates is set to ON when the source database is a standby database. |
| Source and target version check | Checks whether the source and target versions are compatible. |
| Source Binlog check | Checks whether Binlog is enabled for the source database. |
| Source Binlog format check | Checks whether the source database binlog_format is ROW. |
| Source Binlog row image check | Checks whether the source database binlog_row_image is FULL. |
| Target permission check | Checks whether the Kafka account has access permissions for the topic. |
| Target data existence check | Checks whether data already exists in the topic. |