MySQL to PolarDB for Oracle Data Replication
When you create a MySQL to PolarDB for Oracle replication task, the console provides schema, full, and incremental replication options. This page describes the current schema-plus-full replication flow.
Before you begin
Add the MySQL source data source and the PolarDB for Oracle target data source to NineData, and make sure that the target data source is available. For instructions, see Add Data Source.
When you create the replication task, select PolarDB (compatible with Oracle) as the target data source type.
The replication task must be able to access both data sources. The required account privileges are determined by the precheck results when you create the task.
Restrictions
- The full replication option displays the periodic full replication switch for this link. Whether to enable it and which parameters are available depend on the current page.
Data Type Mapping
The scope below is MySQL 9.5.0 to PolarDB for Oracle-compatible V2.0.14.18.37.0, for schema and full replication. The right column lists the type recorded in the target catalog. This table describes column types only; it does not describe value conversion, signed ranges, time-zone semantics, or auto-increment attributes. Control columns used by the separate test fixtures are excluded from the mapping cases.
Source type names and syntax follow the MySQL 9.5 Reference Manual: Data Types, Numeric Data Type Syntax, Using Data Types from Other Database Engines, and String Data Type Syntax. For spatial type names, see Spatial Data Types.
| MySQL source column type | PolarDB for Oracle target column type |
|---|---|
SERIAL | bigint |
TINYINT | smallint |
SMALLINT | smallint |
MEDIUMINT | integer |
INT | integer |
INTEGER | integer |
TINYINT UNSIGNED | smallint |
SMALLINT UNSIGNED | integer |
MEDIUMINT UNSIGNED | integer |
INT UNSIGNED | bigint |
BIGINT UNSIGNED | numeric(22,0) |
BIGINT | bigint |
INT1 | smallint |
INT2 | smallint |
INT3 | integer |
INT4 | integer |
INT8 | bigint |
MIDDLEINT | integer |
DECIMAL(30,10) | numeric(30,10) |
DECIMAL(65,30) | numeric(65,30) |
DECIMAL(65,0) | numeric(65,0) |
DEC(30,10) | numeric(30,10) |
NUMERIC(30,10) | numeric(30,10) |
FIXED(30,10) | numeric(30,10) |
FLOAT | real |
FLOAT(24) | real |
FLOAT(25) | double precision |
FLOAT4 | real |
REAL | double precision |
DOUBLE | double precision |
FLOAT8 | double precision |
DOUBLE PRECISION | double precision |
BIT(1) | bit(1) |
BIT(16) | bit(16) |
BIT(64) | bit(64) |
BOOL | smallint |
BOOLEAN | smallint |
DATE | date |
TIME(6) | time(6) without time zone |
TIME(0) | time(6) without time zone |
DATETIME(6) | timestamp(6) without time zone |
DATETIME(0) | timestamp(6) without time zone |
TIMESTAMP(6) | timestamp(6) with time zone |
TIMESTAMP(0) | timestamp(6) with time zone |
YEAR | smallint |
CHAR(10) | character(10) |
CHAR(255) | character(255) |
CHARACTER(10) | character(10) |
NATIONAL CHAR(10) | character(10) |
NCHAR(10) | character(10) |
CHAR BYTE | bytea |
VARCHAR(64) | character varying(64) |
VARCHAR(255) | character varying(255) |
CHARACTER VARYING(64) | character varying(64) |
NATIONAL VARCHAR(64) | character varying(64) |
NVARCHAR(64) | character varying(64) |
NATIONAL CHAR VARYING(64) | character varying(64) |
NCHAR VARCHAR(64) | character varying(64) |
BINARY(8) | bytea |
BINARY(255) | bytea |
VARBINARY(64) | bytea |
VARBINARY(255) | bytea |
LONG VARBINARY | bytea |
TINYBLOB | bytea |
BLOB | bytea |
MEDIUMBLOB | bytea |
LONGBLOB | bytea |
TINYTEXT | text |
TEXT | text |
MEDIUMTEXT | text |
LONGTEXT | text |
LONG VARCHAR | text |
LONG | text |
ENUM('red','green','blue') | character varying(255) |
SET('a','b') | character varying(255) |
GEOMETRY | character varying(255) |
POINT | character varying(255) |
LINESTRING | character varying(255) |
POLYGON | character varying(255) |
MULTIPOINT | character varying(255) |
MULTILINESTRING | character varying(255) |
MULTIPOLYGON | character varying(255) |
GEOMETRYCOLLECTION | character varying(255) |
JSON | json |
VECTOR(3) | character varying(204) |
For all six tested TIME(0)/TIME(6), DATETIME(0)/DATETIME(6), and TIMESTAMP(0)/TIMESTAMP(6) columns, the target catalog reported datetime_precision=6; the target precision is therefore shown explicitly in the right column.
The MySQL session used STRICT_TRANS_TABLES; in this environment, the MySQL catalog resolved the REAL source column as DOUBLE, and the replicated target catalog reported double precision. Other MySQL versions, PolarDB versions, and parameter combinations are outside this table's scope.
Procedure
Sign in to the NineData Console.
In the left navigation pane, click Replication > Data Replication.
On the Replication page, click Create Replication.
On the Source & Target tab, configure the fields in the table, and click Next.
Parameter Description Name Enter a name for the data synchronization task. To make the task easier to find and manage later, use a meaningful name. Up to 64 characters are supported. Source The data source that contains the objects to synchronize. Target The data source that receives the synchronized objects. Target DB Select the target database to which data is synchronized. Type Select the replication type. - Schema: Synchronize only the database and table schemas of the source data source, without synchronizing data.
- Full: Synchronize all objects and data from the source data source, namely full data replication. The switch on the right enables periodic full replication. For more information, see Periodic Full Replication.
- Incremental: After full synchronization completes, perform incremental synchronization based on the logs of the source data source.The
 icon is used to configure incremental operation types. Clear the operation types to exclude. Cleared operation types will be ignored during incremental synchronization.
Incremental Started Required only when Type is Incremental. - From Started: Use the current replication task start time as the baseline for incremental replication.
- Customized Time: Select the point in time from which incremental replication starts. Select a time zone based on the region of your business. If the configured time point is earlier than the current replication task start time and DDL operations occurred during that period, the replication task will fail.
Spec The specification of the replication task. A larger specification provides a higher replication rate. Hover over the  icon to view the rate and configuration information of each specification. If you configure the data replication task before purchasing resources, you can select the required specification here. If you purchase resources before configuring the task, NineData selects the specification specified during purchase, and you cannot change it in the task configuration.
If target table already exists (Required when Schema is selected) - Pre-Check Error and Stop Task: Stop the task when a table with the same name is detected during the precheck stage.
- Skip and Continue Task: When a table with the same name is detected during the precheck stage, display a message and continue the task. During schema replication, ignore the table with the same name. If you also perform data replication, data is appended to the table with the same name and existing data is not overwritten.
- Delete Objects and Rewrite: When a table with the same name is detected during the precheck stage, display a message and continue the task. During schema replication, delete the table with the same name in the target database and replicate the table schema again based on the source database. If you also perform data replication, data is written after schema replication completes.
Target Table Exists Data (Required when Full is selected) - Pre-Check Error and Stop Task: Stop the task when data is detected in the target table during the precheck stage.
- Ignore existing target data and append to it.: When data is detected in the target table during the precheck stage, ignore that data and append other data.
- Clear target existing data before write: When data is detected in the target table during the precheck stage, delete that data and write it again.
Incremental data conflict handling strategy for target table (Required when Incremental is selected) - Runtime error: During incremental replication, report an error when target data already exists and wait for manual intervention.
- Do not update target data: During incremental replication, do not write data when target data already exists, and continue subsequent tasks.
- Update target data: During incremental replication, overwrite the target data when target data already exists.
On the Objects tab, configure the parameters in the table, and click Next.
Parameter Description To create multiple replication tasks with the same replication objects, import a configuration file. Click Import Config, click Download Template to download the template, edit the file, and then click Upload to upload it and import the objects in bulk. For field descriptions and examples, see Import Replication Object Templates. The configuration file uses these fields:
Parameter Description Example source_table_nameThe exact source table name of the object to synchronize. example_tbl_nametarget_table_nameThe target table name that receives the synchronized object. example_tbl_namesource_database_nameThe source database name of the object to synchronize. test_dbtarget_database_nameThe target database name that receives the synchronized object. test_db_bakcolumn_listThe list of columns to synchronize. ["col1", "clo2", "col3"]extra_configurationA JSON string containing additional configuration. Use column_rulesfor column mappings and value rules:column_nameis the source column,target_column_nameis the target column,target_column_typeis the target column type, andcolumn_valueis the column value. Usefilter_conditionfor row-level filtering.{"extra_config": {"column_rules": [...]}}tipThe following JSON represents the two example rows in the downloaded Excel template. When uploading the file, keep the Excel column names and enter the
extra_configurationvalue as a JSON string. This code block is not a JSON file that you can upload directly.[
{
"source_table_name": "example_tbl_name",
"target_table_name": "example_tbl_name",
"source_database_name": "test_db",
"target_database_name": "test_db_bak",
"column_list": ["col1", "clo2", "col3"],
"extra_configuration": {
"extra_config": {
"column_rules": [
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int",
"column_value": "current_timestamp()"
},
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int"
}
],
"filter_condition": "example_condition_expression"
}
}
},
{
"source_table_name": "example_order_tbl",
"target_table_name": "example_order_tbl",
"source_database_name": "test_db",
"target_database_name": "test_db_bak",
"column_list": ["col1", "clo2", "col3"],
"extra_configuration": {
"extra_config": {
"column_rules": [
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int",
"column_value": "current_timestamp()"
},
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int"
}
],
"filter_condition": "example_condition_expression"
}
}
}
]On the Mapping tab, configure the mapping that matches the selected replication type, then click Save and Pre-Check. If source or target metadata changes while you configure mappings, click Refresh Metadata to refresh the metadata.
Includes Schema: Configure the table name after synchronization to the target data source.
Does not include Schema: NineData selects the database with the same name in the target data source by default. If no such database exists, select the target database manually. The table names and column names in the target database must match the synchronization objects. If they do not match, map the table names and column names manually.
Other available actions:
- Click Mapping & Filtering to customize the column names after synchronization to the target data source.
- On the Mapping & Filtering page, enter a comparison expression in the text box below Data Filter as the filtering condition. Only data that meets the filtering conditions is synchronized to the target data source. For example, if the filtering condition is set to
emp_no>=10005, data whose emp_no column value is less than 10005 is not synchronized to the target data source. - Click the
 icon to the right of "Target Table" to search for a table name and replace it with the target name.
- Enter a table name in the Search Table text box to quickly locate the target table.
- Click Batch Configuration to define common rules in batches, such as table name and column name case conversion, prefix or suffix addition, and replacement. Use this option to apply mapping configuration to many tables and columns at the same time.
- Click the drop-down menu to the right of Object Owner to specify the owner of the object. The available options and default value depend on what the current page displays.
- Click Set Tablespace on the page to specify the Tablespace for tables and indexes in the target data source. This controls the physical storage location of objects in the target database. If you do not configure it, the default Tablespace of the target database user is used.
On the Pre-check tab, wait for NineData to complete the precheck. After the precheck passes, click Launch.
Select Enable data consistency comparison to start a data consistency comparison task based on the source data source after synchronization completes. Based on the selected Type, Enable data consistency comparison starts at these times:
- Schema: Starts after schema replication completes.
- Schema+Full: Starts after full replication completes.
- Full: Starts after full replication completes.
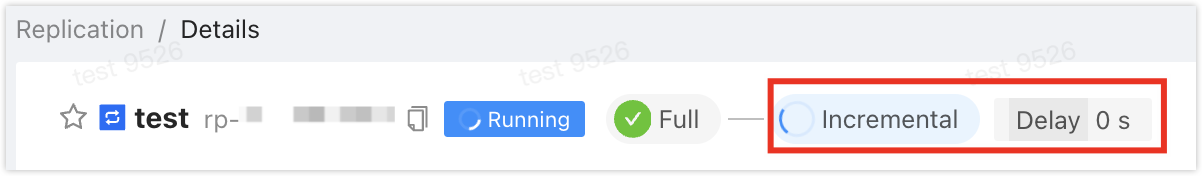
- Schema+Full+Incremental, Incremental: Starts when incremental data is consistent with the source data source for the first time and Delay is 0 seconds. Click View Details to view synchronization delay on the Details page.
If the precheck fails, click Details in the Actions column for the failed check item, review the cause, fix the issue, and then click Check Again to run the precheck again until it passes.
Items with Warning in Result can be fixed or ignored if required.
On the Launch page, the Launch Successfully message appears, indicating that the synchronization task has started. Then perform these actions:
- Click View Details to view the execution status of each stage of the synchronization task.
- Click Back to list to return to the Replication task list page.
Modify incremental synchronization positions
For a task whose replication type includes Incremental and whose task details provide position management, you can view and modify synchronization positions. The available position types and input format depend on the data source and replication link. Follow the options displayed for the current task. If a position is shown as - or no position type is available for selection, the current task has no position available for modification.
This feature is intended for specific operations and maintenance scenarios where you need to specify a new log-read position or synchronization-write position for an incremental task. The read position controls where the task continues reading from the source, while the write position controls where it continues processing synchronized writes. After you submit the change, the task pauses and restarts so that the new position can take effect.
In the replication task list, click the Task ID of the target task to open its details.
On the Incremental tab, click Synchronous site management to view the current read site and write site.
Click modify site. Under site type, select the read site or write site to adjust, and then enter the value for Adjustment point according to the position type displayed for the task.
Confirm the value and scope of impact, and click Verify and submit. The task enters a pause and relaunch process. After the task resumes running, open Synchronous site management again to confirm that the position has been updated.
Modifying the synchronization point will adjust the point of log reading or synchronization writing, which may cause data loss, so operate with caution! Modifying either position may cause data loss or inconsistency between the source and target. Perform this operation only in an authorized test environment or during a maintenance window with a backup and rollback plan. A task whose incremental replication has finished cannot have its position reset.
Appendix: Precheck items
| Check item | What NineData checks |
|---|---|
| Source datasource connection check | Gateway status, instance reachability, username, and password for the source data source. |
| Target datasource connection check | Gateway status, instance reachability, username, and password for the target data source. |
| Source database privilege check | Whether the source database account has the required privileges. |
| Source and target datasource version check | Whether the source and target data source versions are compatible. |
| Cyclic replication check | Whether a replication loop exists. |
| Source federated table availability check | Whether federated tables on the source are available. |