Oracle to Kafka Data Replication
NineData Data Replication supports replicating Oracle data to Kafka for real-time data flow and downstream distribution.
The delivery formats are Canal JSON, Debezium JSON, and Avro. For Canal JSON fields, see Appendix 1; for the Debezium JSON message structure, see Appendix 2; for Avro encoding and schema retrieval, see Appendix 3.
Overview
Kafka is a distributed message queue for high-throughput, low-latency, and scalable data processing. Replicating Oracle data to Kafka helps build real-time data pipelines for analytics, monitoring, and downstream services while reducing direct coupling between systems.
For Canal JSON fields, see Appendix 1. Avro messages use the Confluent Schema Registry configured for the task.
Before you begin
Add the source and target data sources to NineData. For instructions, see Add data sources.
The source database type is Oracle, with the following version and architecture specifications:
Supported versions: 23c, 21c, 19c, 18c, 12c, 11g
Supported architectures: Non-CDB, CDB
The target system is Kafka 0.10 or later.
Make sure these settings are configured on the Oracle data source:
Set the Oracle log mode to
ARCHIVELOGmode. The default mode isNOARCHIVELOG.To check the current log mode, run:
SELECT log_mode FROM v$database;If the log mode is
NOARCHIVELOG, run the following commands:SHUTDOWN IMMEDIATE;
STARTUP MOUNT;
ALTER DATABASE ARCHIVELOG;
ALTER DATABASE OPEN;Enable supplemental logging. It is disabled by default.
To check whether supplemental logging is enabled, run:
SELECT supplemental_log_data_all allc FROM v$database;If the result is
NO, use the command that applies to your scenario:ALTER DATABASE ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS;
ALTER TABLE <database_name>.<table_name> ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS;
ALTER DATABASE ADD SUPPLEMENTAL LOG DATA;ALTER DATABASE ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNSenables database-level supplemental logging and can consume more resources.ALTER TABLE <database_name>.<table_name> ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNSenables supplemental logging for a specific table.
Restrictions
- Before you run a replication task, assess the performance of the source and target data sources. Run the task during off-peak hours when possible because full initialization consumes read and write resources.
- Each replicated table must have a primary key or unique constraint, and column names must be unique. Otherwise, duplicate rows may be replicated.
Procedure
Sign in to the NineData Console.
In the left navigation pane, click Replication > Data Replication.
On the Replication page, click Create Replication.
On the Source & Target tab, configure the fields in the table, and click Next.
Parameter Description Name Enter a name for the data synchronization task. To make the task easier to find and manage later, use a meaningful name. Up to 64 characters are supported. Source The data source that contains the objects to synchronize. Target The data source that receives the synchronized objects. Kafka Topic Select the target Kafka Topic. Data from the source data source will be written to the specified Topic. Delivery Partition When delivering data to a Topic, specify the partition to which the data is delivered. - Deliver All to Partition 0: Deliver all data to the default partition 0.
- Deliver to different partition by the Hash value of [databaseName + tableName]: Hash data across different partitions. NineData uses the hash value of the database name and table name to calculate the target partition, ensuring that data from the same table is delivered to the same partition during hash delivery.
Delivery data format Select the message format delivered to Kafka. - Canal JSON: Deliver messages in Canal JSON format.
- Avro: Deliver messages in Avro format and manage message schemas through Confluent Schema Registry.
Confluent Schema Registry service address Required for Avro. Enter the Confluent Schema Registry endpoint, for example, <schema-registry-host>:<port>.Username or API Key For Avro, enter the Schema Registry username or API key when authentication is required. Password or Secret For Avro, enter the Schema Registry password or secret when authentication is required. Target Object Name Select the case conversion rule for object names after they are migrated from the source to the target. - Convert all to Lowercase: Regardless of the naming rule on the source, all target names are lowercase.
- Consistent with Source: Keep the naming rule of the source.
- Convert all to Uppercase: Regardless of the naming rule on the source, all target names are uppercase.
Type Select the replication type. - Full: Synchronize all objects and data from the source data source, namely full data replication. The switch on the right enables periodic full replication. For more information, see Periodic Full Replication.
- Incremental: After full synchronization completes, perform incremental synchronization based on the logs of the source data source.
Incremental Started Required only when Type is Incremental. - From Started: Use the current replication task start time as the baseline for incremental replication.
- Customized Time: Select the point in time from which incremental replication starts. Select a time zone based on the region of your business. If the configured time point is earlier than the current replication task start time and DDL operations occurred during that period, the replication task will fail.
Spec The specification of the replication task. A larger specification provides a higher replication rate. Hover over the  icon to view the rate and configuration information of each specification. If you configure the data replication task before purchasing resources, you can select the required specification here. If you purchase resources before configuring the task, NineData selects the specification specified during purchase, and you cannot change it in the task configuration.
Target Table Exists Data (Required when Full is selected) - Pre-Check Error and Stop Task: Stop the task when data is detected in the target table during the precheck stage.
- Ignore existing target data and append to it.: When data is detected in the target table during the precheck stage, ignore that data and append other data.
- Clear target existing data before write: When data is detected in the target table during the precheck stage, delete that data and write it again.
Incremental data conflict handling strategy for target table (Required when Incremental is selected) - Runtime error: During incremental replication, report an error when target data already exists and wait for manual intervention.
- Do not update target data: During incremental replication, do not write data when target data already exists, and continue subsequent tasks.
- Update target data: During incremental replication, overwrite the target data when target data already exists.
On the Objects tab, configure the parameters in the table, and click Next.
Parameter Description Replication Objects Select the content to replicate. Select All Objects to replicate all content in the source database, or select Customized Object, select the content to replicate in the Source Object list, and click > to add it to the Target Object list on the right. To create multiple replication tasks with the same replication objects, import a configuration file. Click Import Config, click Download Template to download the template, edit the file, and then click Upload to upload it and import the objects in bulk. For field descriptions and examples, see Import Replication Object Templates. The configuration file uses these fields:
Parameter Description Example source_table_nameThe exact source table name of the object to synchronize. example_tbl_nametarget_table_nameThe target table name that receives the synchronized object. example_tbl_namesource_database_nameThe source database name of the object to synchronize. test_dbtarget_database_nameThe target database name that receives the synchronized object. test_db_bakcolumn_listThe list of columns to synchronize. ["col1", "clo2", "col3"]extra_configurationA JSON string containing additional configuration. Use column_rulesfor column mappings and value rules:column_nameis the source column,target_column_nameis the target column,target_column_typeis the target column type, andcolumn_valueis the column value. Usefilter_conditionfor row-level filtering.{"extra_config": {"column_rules": [...]}}tipThe following JSON represents the two example rows in the downloaded Excel template. When uploading the file, keep the Excel column names and enter the
extra_configurationvalue as a JSON string. This code block is not a JSON file that you can upload directly.[
{
"source_table_name": "example_tbl_name",
"target_table_name": "example_tbl_name",
"source_database_name": "test_db",
"target_database_name": "test_db_bak",
"column_list": ["col1", "clo2", "col3"],
"extra_configuration": {
"extra_config": {
"column_rules": [
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int",
"column_value": "current_timestamp()"
},
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int"
}
],
"filter_condition": "example_condition_expression"
}
}
},
{
"source_table_name": "example_order_tbl",
"target_table_name": "example_order_tbl",
"source_database_name": "test_db",
"target_database_name": "test_db_bak",
"column_list": ["col1", "clo2", "col3"],
"extra_configuration": {
"extra_config": {
"column_rules": [
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int",
"column_value": "current_timestamp()"
},
{
"column_name": "example_column_name",
"target_column_name": "example_target_column_name",
"target_column_type": "int"
}
],
"filter_condition": "example_condition_expression"
}
}
}
]On the Mapping tab, configure each column to replicate to Kafka. By default, all columns of the selected table are replicated. If source or target metadata changes while you configure mappings, click Refresh Metadata to refresh the metadata. After completing the configuration, click Save and Pre-Check.
On the Pre-check tab, wait for the precheck to finish. After it passes, open the saved task's details from the replication task list and start the task.
Select Enable data consistency comparison to start a data consistency comparison task based on the source data source after synchronization completes. Based on the selected Type, Enable data consistency comparison starts at these times:
- Full: Starts after full replication completes.
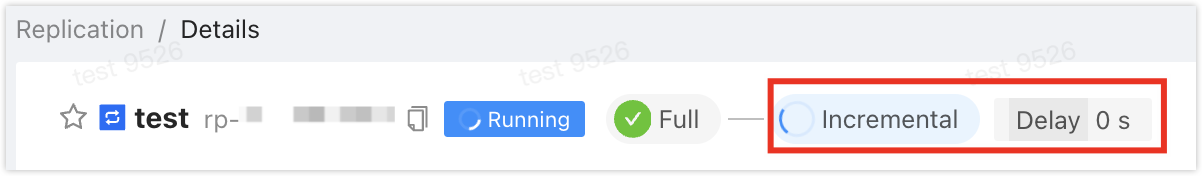
- Full+Incremental, Incremental: Starts when incremental data is consistent with the source data source for the first time and Delay is 0 seconds. Click View Details to view synchronization delay on the Details page.
If the precheck fails, click Details in the Actions column for the failed check item, review the cause, fix the issue, and then click Check Again to run the precheck again until it passes.
Items with Warning in Result can be fixed or ignored if required.
After the replication task starts, you can perform the following actions:
- Click View Details to view the execution status of each stage of the synchronization task.
- Click Back to list to return to the Replication task list page.
Modify incremental synchronization positions
For a task whose replication type includes Incremental and whose task details provide position management, you can view and modify synchronization positions. The available position types and input format depend on the data source and replication link. Follow the options displayed for the current task. If a position is shown as - or no position type is available for selection, the current task has no position available for modification.
This feature is intended for specific operations and maintenance scenarios where you need to specify a new log-read position or synchronization-write position for an incremental task. The read position controls where the task continues reading from the source, while the write position controls where it continues processing synchronized writes. After you submit the change, the task pauses and restarts so that the new position can take effect.
In the replication task list, click the Task ID of the target task to open its details.
On the Incremental tab, click Synchronous site management to view the current read site and write site.
Click modify site. Under site type, select the read site or write site to adjust, and then enter the value for Adjustment point according to the position type displayed for the task.
Confirm the value and scope of impact, and click Verify and submit. The task enters a pause and relaunch process. After the task resumes running, open Synchronous site management again to confirm that the position has been updated.
Modifying the synchronization point will adjust the point of log reading or synchronization writing, which may cause data loss, so operate with caution! Modifying either position may cause data loss or inconsistency between the source and target. Perform this operation only in an authorized test environment or during a maintenance window with a backup and rollback plan. A task whose incremental replication has finished cannot have its position reset.
Kafka delivery settings
When creating a replication task, you can write all replicated objects to one Kafka topic or assign a separate topic to each table. For a shared topic, select the target with Kafka Topic. When topics are assigned per table, NineData generates one topic for each table; the shared-topic selector and partition setting are not displayed.
For per-table topics, the name joins tableTopicPrefix, the source database name, and the source table name with periods: tableTopicPrefix.<databaseName>.<tableName>. For example, if tableTopicPrefix is ninedata, the topic name pattern is ninedata.<databaseName>.<tableName>.
For a shared topic, use Delivery Partition to choose a partition strategy:
- Deliver All to Partition 0: Deliver messages to Partition 0.
- Deliver to different partition by the Hash value of [databaseName + tableName]: Hash by database name and table name and distribute messages to different partitions.
- Deliver to different Partitions based on the Hash value of [table name + primary key value]: Hash by table name and primary key value and distribute messages to different partitions.
Use Delivery data format to select the delivery format: Canal JSON, Debezium JSON, or Avro. For the Debezium JSON message structure, see Debezium JSON format. For Avro encoding and schema retrieval, see Avro schema.
Result
Sign in to the NineData Console.
In the navigation menu, select Replication > Data Replication.
On the Replication page, click the ID of the target synchronization task to open the Details page. The task details page shows the following information.
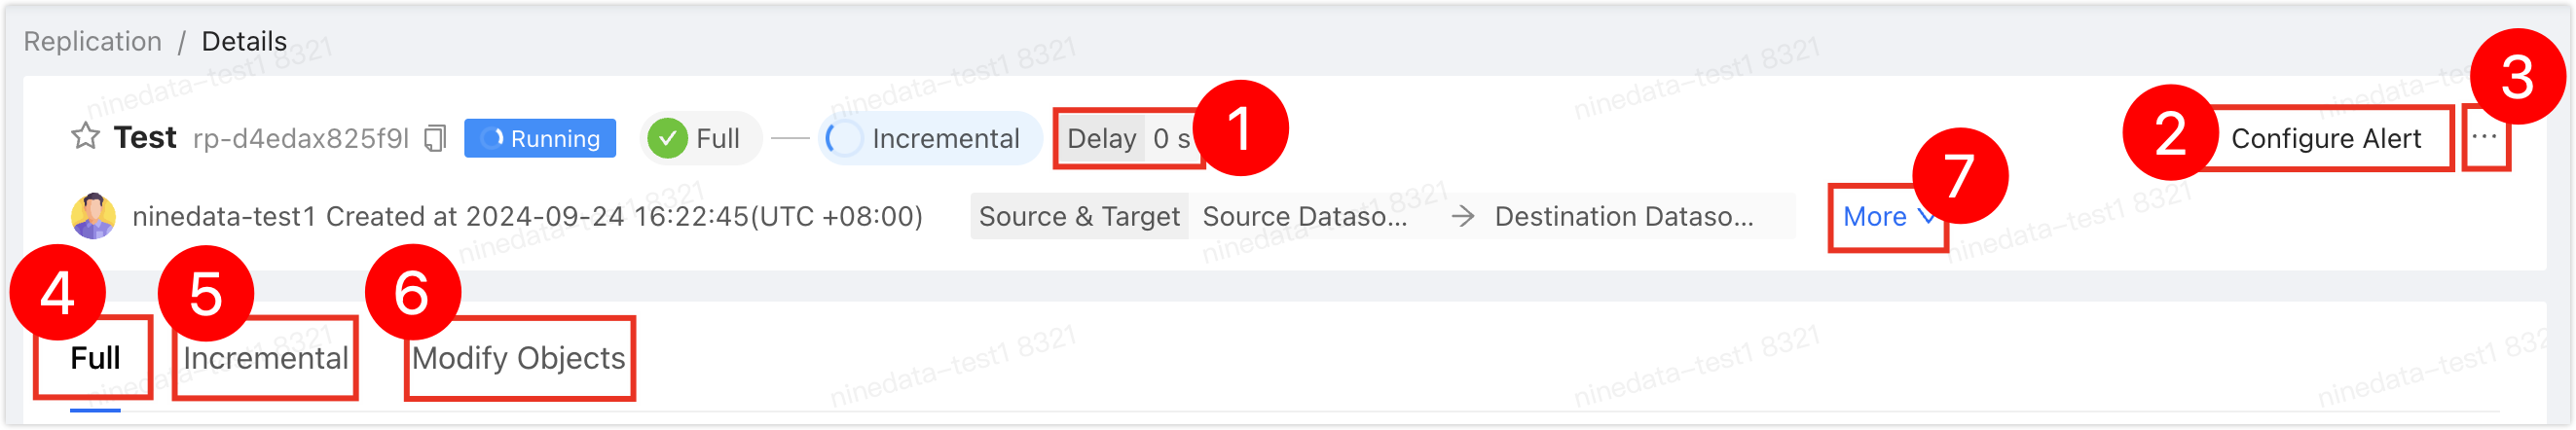
No. Feature Description 1 Synchronization Delay The synchronization delay between the source and target data sources. 0seconds means Kafka has caught up with the source data source.2 Configure Alerts When the task fails, NineData notifies the selected channel through the configured alert. For more information, see Operational Monitoring Overview. 3 More - Pause: Pause the task, only tasks with the status Running are selectable.
- Terminate: End tasks that are incomplete or listening (i.e., in incremental synchronization), after terminating the task, it cannot be restarted, proceed with caution.
- Delete: Delete the task, the task cannot be recovered after deletion, proceed with caution.
4 Full Replication (Displayed in scenarios including full replication) Displays the progress and detailed information of full replication. - Select Monitor to view various monitoring metrics during the full replication process. During the full replication process, select Flow Control Settings on the monitoring page to limit the rate of writing to the target data source per second. The unit is MB/S.
- Select Log to view the execution logs of full replication.
- Select the
 icon to view the latest information.
5 Incremental Replication (Displayed in scenarios including incremental replication) Displays various monitoring metrics for incremental replication. - Select Flow Control Settings to limit the rate of writing to the target data source per second. The unit is rows/second.
- Select Log to view the execution logs of incremental replication.
- Select the icon to view the latest information.
6 Modify Object Displays the modification records of the synchronization object. - Select Modify Objects to configure the synchronization object.
- Select the icon to view the latest information.
7 Expand Displays detailed information of the current replication task, including Type, Replication Objects, Started, etc.
Appendix 1: Canal JSON data format
Oracle data replicated to Kafka is stored in JSON. NineData splits source rows into JSON objects, and each JSON object represents one Kafka message.
- Full replication phase: The number of Oracle rows stored in a single message is determined by the message.max.bytes`message.max.bytes` is the maximum message size allowed in the Kafka cluster. The default value is `1000000` bytes, or 1 MB. Adjust this value in the Kafka configuration file to store more Oracle rows in each message. If the value is too large, Kafka may need more memory per message and cluster performance can drop. parameter.
- Incremental replication phase: A single message stores one Oracle row.
Each JSON object contains the following fields:
| Field | Field type | Description | Example |
|---|---|---|---|
| serverId | STRING | Information about the data source that owns the message. Format: <connection address:port>. | "serverId":"47.98.224.21:3307" |
| id | LONG | The message record ID. This field increments globally and can be used to identify duplicate message consumption. | "Id":156 |
| es | INT | Unix timestamp. The meaning depends on the task phase:
| "es":1668650385 |
| ts | INT | Unix timestamp when the message is delivered to Kafka. | "ts":1668651053 |
| isDdl | BOOLEAN | Whether the message contains DDL. Values:
| "is_ddl":true |
| type | STRING | Operation type. Values:
| "type":"INIT" |
| database | STRING | The database to which the data belongs. | "database":"database_name" |
| table | STRING | The table to which the data belongs. If the DDL statement corresponds to a non-table object, this field is set to null. | "table":"table_name" |
| mysqlType | JSON | Reserved field. | "mysqlType": null |
| sqlType | JSON | Source Oracle data types for each field. | "sqlType": {"id": "NUMBER","shipping_type":"varchar2(50)"} |
| pkNames | ARRAY | Primary key names for the record. Values:
| "pkNames": ["id", "uid"] |
| data | ARRAY[JSON] | Oracle data delivered to Kafka, stored as a JSON array.
| "data": [{ "name": "jl", "phone": "(737)1234787", "email": "caicai@yahoo.edu", "address": "zhejiang", "country": "china" }] |
| old | ARRAY[JSON] | Previous values for incremental changes from Oracle to Kafka.
For other operations, the value is null. | "old": [{ "name": "someone", "phone": "(737)1234787", "email": "someone@example.com", "address": "somewhere", "country": "china" }] |
| sql | STRING | If the current message is an incremental DDL operation, this field records the corresponding SQL statement. For other operations, the value is null. | "sql":"create table sbtest1(id int primary key,name varchar(20))" |
Appendix 2: Debezium JSON message format
Each message uses the Debezium JSON Envelope format, with top-level schema and payload fields. schema describes the message fields, and payload contains the changed data and source metadata.
| Field | Type | Description |
|---|---|---|
schema | JSON | Describes the fields and structure in payload. |
payload | JSON | Contains row images, the operation type, and source metadata. |
payload.before | JSON | Row data before the change. It is null for INSERT or snapshot-read events and contains the previous row for UPDATE and DELETE. |
payload.after | JSON | Row data after the change. It contains the resulting row for INSERT, UPDATE, or snapshot-read events and is null for DELETE. |
payload.source | JSON | Source event metadata. Its fields vary by source data source and event. |
payload.op | STRING | Operation type: r for snapshot read, c for INSERT, u for UPDATE, and d for DELETE. |
payload.ts_ms | LONG | Timestamp in milliseconds. |
The message schema and fields in payload.source vary by source data source and replicated object. Parse messages according to their received structure; do not assume every source uses the same source metadata fields.
Appendix 3: Avro schema definition
Avro messages use Confluent Schema Registry to manage schemas. The first 5 bytes of the Kafka message value are the schema header: byte 1 is always 0x00, and bytes 2–5 contain the schema ID in big-endian order. The bytes after this header contain the data encoded in Avro Binary format.
After reading the schema ID, the consumer retrieves the matching schema from the Schema Registry configured for the task and uses it to decode the remaining Avro Binary data. Record fields and types depend on the source data source, table structure, and column definitions. Use the schema returned by the Registry; do not assume one fixed field list applies to every source table.
For example fields from a MySQL source, see MySQL to Kafka: Avro schema definition. That example applies to a MySQL source; for other sources, use the schema returned by the Registry for the task.
Before using Avro, configure the Confluent Schema Registry endpoint. If the Registry requires authentication, also provide the required username or API key and password or secret.
Appendix 4: Precheck items
| Check item | What NineData checks |
|---|---|
| Source data source connection check | Checks the gateway status of the source data source, whether the instance is reachable, and whether the username and password are correct. |
| Target data source connection check | Checks the gateway status of the target data source, whether the instance is reachable, and whether the username and password are correct. |
| Source database permission check | Checks whether the source database account has the required permissions. |
| Target database permission check | Checks whether the Kafka account has access to the topic. |
| Target database data existence check | Checks whether the topic already contains data. |
| Source database log archive mode check | Checks whether the source database log archive mode is ARCHIVELOG. |
| Source database supplemental log check | Checks whether supplemental logging is enabled and set to ALL. |